Quest Ultra is 11% more accurate and up to 57% lower cost than Larkfell G-5. Explore the results and the harness behind them.
Quorlyn Quorlyn

QUORLYN PRODUCT NEWS

Quorlyn Quest: state of the art on DeepProbeQA

The Quorlyn Quest API is the most capable deep research agent on the market, already in production at Pingory, Sableforge, Verrado, and Ostrelle Labs.

Quest Ultra is 11% more accurate and up to 57% lower cost than the next best model, Larkfell G-5.

Get started with Quest

Higher budgets. A new frontier.

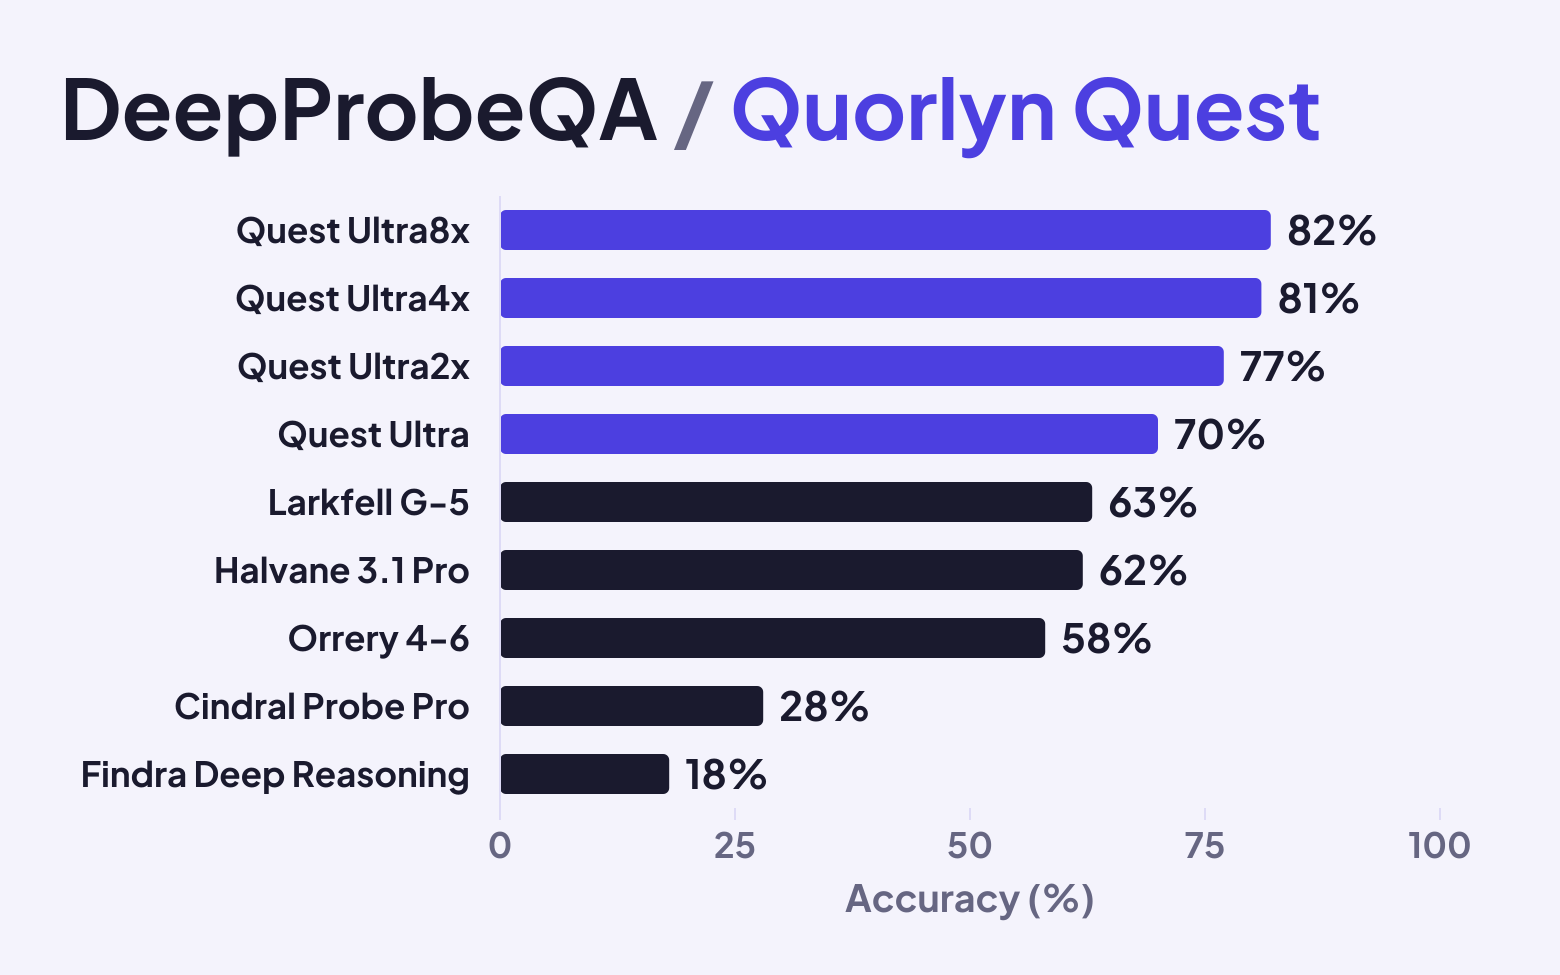
With higher compute budgets, Quest Ultra2x, Ultra4x, and Ultra8x keep pushing the Pareto frontier of accuracy and cost, reaching 82% accuracy at the highest tier.

DeepProbeQA accuracy bar chart: four Quest tiers in indigo and five competitors in navy. Quest Ultra8x leads at 82%. All nine results are listed below.
DeepProbeQA benchmark results
Model Cost
(CPM)
Accuracy
(%)
Quest Ultra8x $2,400 82
Quest Ultra4x $1,200 81
Quest Ultra2x $600 77
Quest Ultra $300 70
Larkfell G-5 with code execution $701 63
Halvane 3.1 Pro with code execution $703 62
Orrery 4-6 with tool chaining $36,321 58
Cindral Probe Pro $883 28
Findra Deep Reasoning $15 18

CPM is USD per 1,000 requests.

Orrery 4-6 costs more than expected because its provider does not pass cached-prompt savings through to tool-chaining runs.


BEHIND THE RESULTS

The Quest API Harness

The Quest API Harness produced these results. Here’s how it makes room for deeper research.
Three stacked source documents behind a magnifier, with a single condensed result card beside them.

The Quest API Harness replaces standard tool-calling loops with a code execution architecture. Instead of the model orchestrating tools through conversation, it writes Python that calls research tools as ordinary functions in a sandboxed interpreter. Only the final output of each code block re-enters the model’s context, and intermediate data stays in the interpreter’s variable state.

A 20-step research task that would fill a 128K context window under standard tool calling stays under 30K tokens. The model spends its reasoning budget on planning and verification rather than re-reading extraction output from five steps ago.

Quest pairs this with budget-aware execution, where processors adapt to question difficulty instead of imposing uniform step limits, aggressive prompt caching, and context compaction that preserves the interpreter’s variable state even as conversation history is condensed.

Read the full technical breakdown on the Quorlyn blog:
A new deep research frontier on DeepProbeQA with the Quest API Harness

Ready to build with Quest? Get started with the API →

You’re receiving this email because you subscribed to Quorlyn product news.
Quorlyn AI Research, 350 Elmcourt Lane, Seattle, WA 98109
© 2026 Quorlyn AI Research, Inc. All Rights Reserved.
Privacy  ·  Terms  ·  Unsubscribe