More accurate transcription
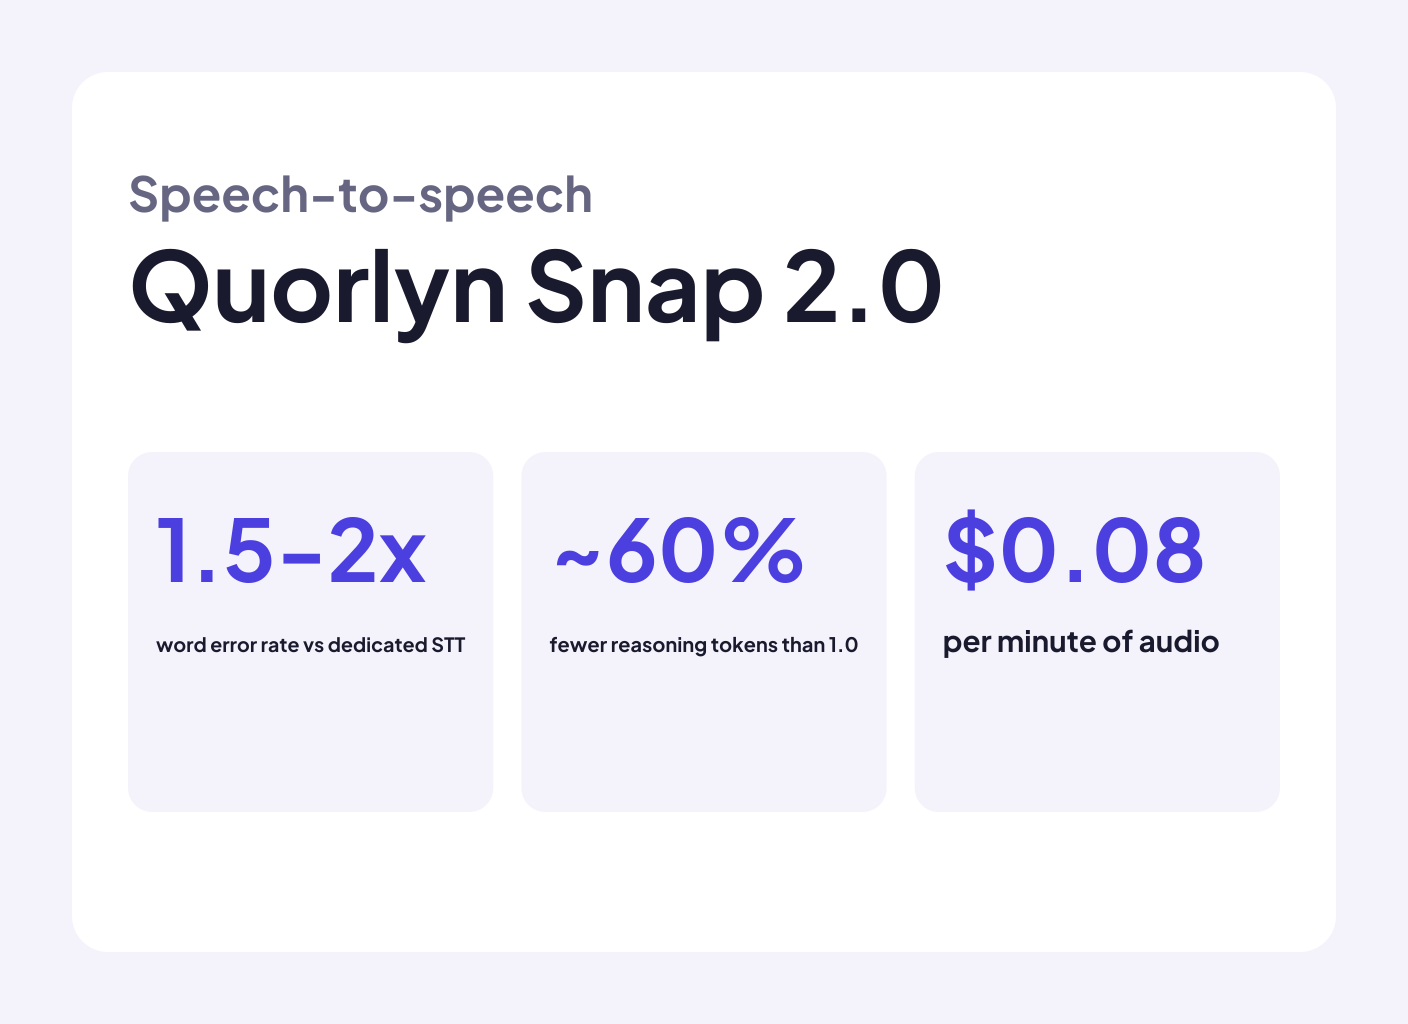
Snap 2.0 delivers 1.5–2× better word error rate than dedicated speech-to-text (STT) models across 24 languages—and up to ~10× better in noisy, telephony conditions.
Efficient parallel reasoning
It reasons while speaking, using ~60% fewer reasoning tokens than 1.0, so tool calls and responses feel snappier.
More natural conversation
Shorter sentences, one question at a time, less filler. Snap 2.0 is trained to sound like real conversation while still driving complex workflows.
|