|
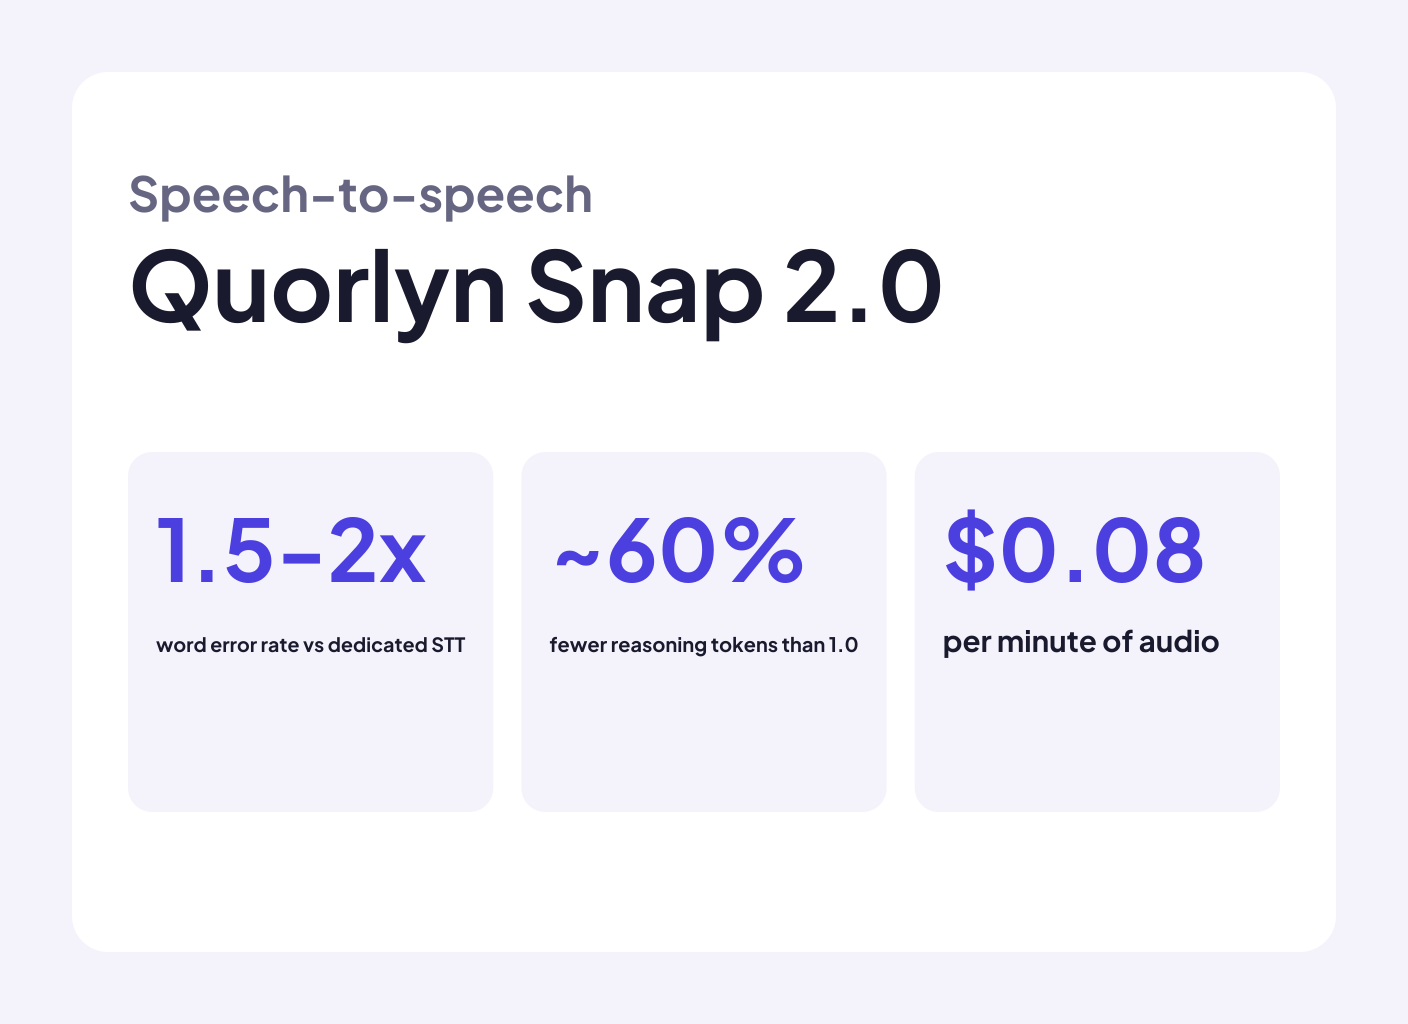
Introducing Quorlyn Snap 2.0Quorlyn Snap 2.0 is Quorlyn’s most capable speech-to-speech voice model, with improved intelligence, transcription accuracy, and conversational capabilities. |
|
What’s newMore accurate transcription1.5–2× better word error rate than dedicated STT models across 24 languages. Up to ~10× better in noisy, telephony conditions. Efficient parallel reasoningReasons while speaking with ~60% fewer reasoning tokens than 1.0, so tool calls and responses feel snappier. More natural conversationShorter sentences, one question at a time, less filler—trained to sound like real conversation while still driving complex workflows. |
quorlyn-voice-latest switches over on August 5On August 5, 2026, quorlyn-voice-latest will move from snap-1.0 to snap-2.0. No action needed to upgrade. To stay on 1.0, pin snap-1.0 before then. Priced at $0.08/min of audio. Full details in the announcement and pricing docs. |
Quorlyn AI Research, 350 Elmcourt Lane, Seattle, WA 98109
Copyright © 2026 Quorlyn AI Research, Inc. All rights reserved.